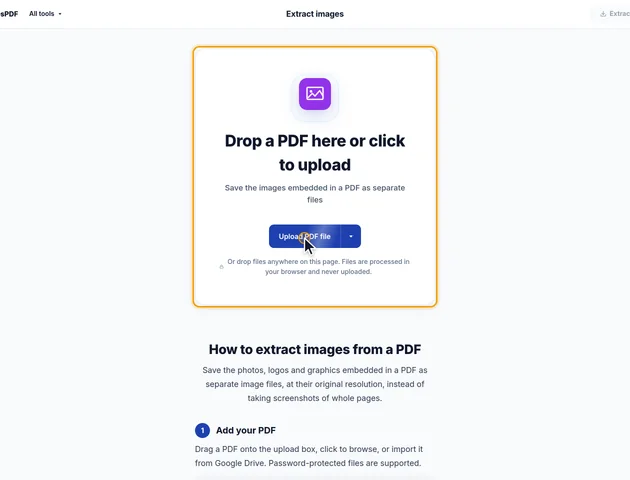
Drop a PDF here or click to upload
Save the images embedded in a PDF as separate files
Or drop files anywhere on this page. Files are processed in your browser and never uploaded.
Save the photos, logos and graphics embedded in a PDF as separate image files, at their original resolution, instead of taking screenshots of whole pages.
Drag a PDF onto the upload box, click to browse, or import it from Google Drive. Password-protected files are supported.
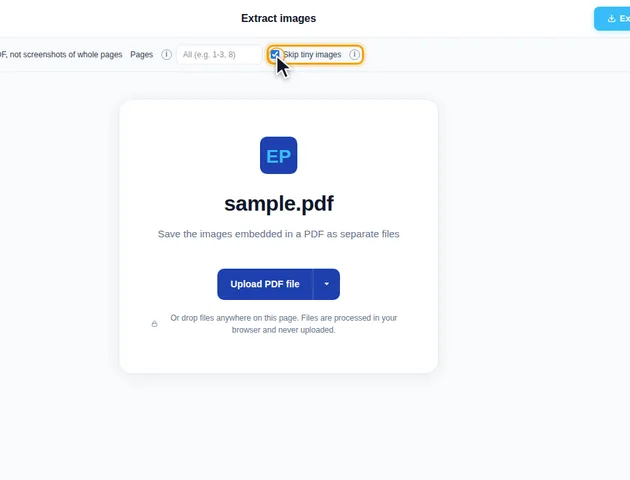
Leave Pages empty to scan the whole document, or enter pages such as 1-3, 8. Skip tiny images is on by default and leaves out icons, bullets and other images smaller than 20 pixels on either side.
Click Extract images. Each image found is shown with its page number. Save downloads a single image, and the x button leaves an image out of the download. Undo and redo reverse these changes.
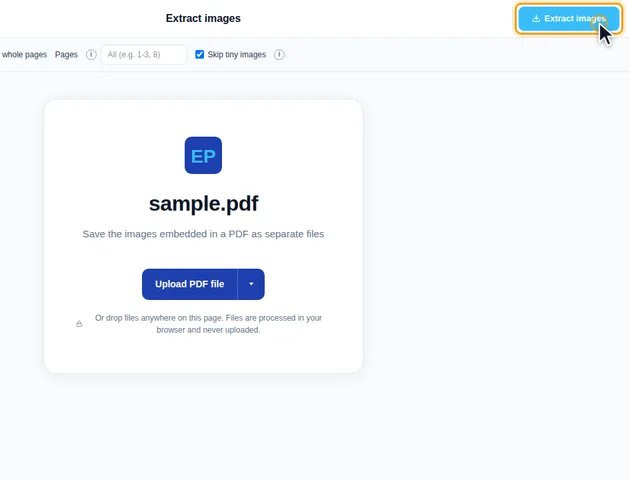
Click the Download button in the header. A single image downloads as is; several are packed into one ZIP file. On the results screen you can also save to Google Drive, open another tool, or delete the files.
Most JPEG photos are saved exactly as they are stored in the PDF, with no re-compression. Other images, including CMYK JPEGs, are decoded and saved as lossless PNG files.
Each image object in a PDF carries a note about how its pixels are compressed and what color system they use. Extract images reads that note before deciding what to save.
A picture is copied out byte for byte as a .jpg only when all of these are true:
Anything else is drawn by pdf.js onto a canvas at its own pixel size, with a transparent background, and saved as a PNG. That covers palette images, Lab colors, JPEG 2000 photos and black-and-white fax-style scans, as well as the masked and CMYK cases.
A PNG made this way always has 8 bits per channel plus an alpha channel. That's fine for a logo, but it can balloon other things:
None of this loses detail you could see, but a ZIP of extracted scans can easily outweigh the PDF it came from. If you only need to read those pages, rendering them with PDF to JPG and the "Black and white" color setting usually gives smaller files.
Some image objects aren't really pictures. A stencil mask is a 1-bit shape with no color of its own: the page fills it with whatever color is current, a bit like spraying paint through a cut-out. Extract images leaves these out, since the file has only the outline.
This matters for scans saved with heavy "mixed" compression, which some scanners and PDF makers use to shrink color documents. The text is often kept as a sharp black stencil over a softer, low-resolution background picture. You'll get the background, sometimes with the text missing. For those files, render the page instead.
The tool walks each page's own content and any reusable graphics that content calls on, such as a letterhead or a page imported from another PDF. It doesn't open annotations. A photo added as a stamp comment, or a signature image placed by an app that stores it as an annotation, sits outside the page content and won't be listed.
The same applies to images in form field appearances, such as a photo box on an ID application form.
There is no fixed limit. The file is processed in your browser, so the practical limit is your device's memory.
Yes. It works in any modern browser, including on phones and tablets.
Yes. The PDF is processed in your browser and is not uploaded to a server.
